An AI-powered entry in TopGit's GitHub warehouse: openai/CLIP, 34.3k stars, AI Tools, Jupyter Notebook. CLIP (Contrastive Language-Image Pretraining), Predict the most relevant text snippet given an image
Snapshot summary built from the project's own GitHub metadata — there's no written TopGit review yet. The page will update automatically when a full review is published.
WHY NO REVIEW YET
TopGit writes full reviews for the most-starred, most-requested repositories. This page is a snapshot until then — see the READ ME tab for the original README in full.
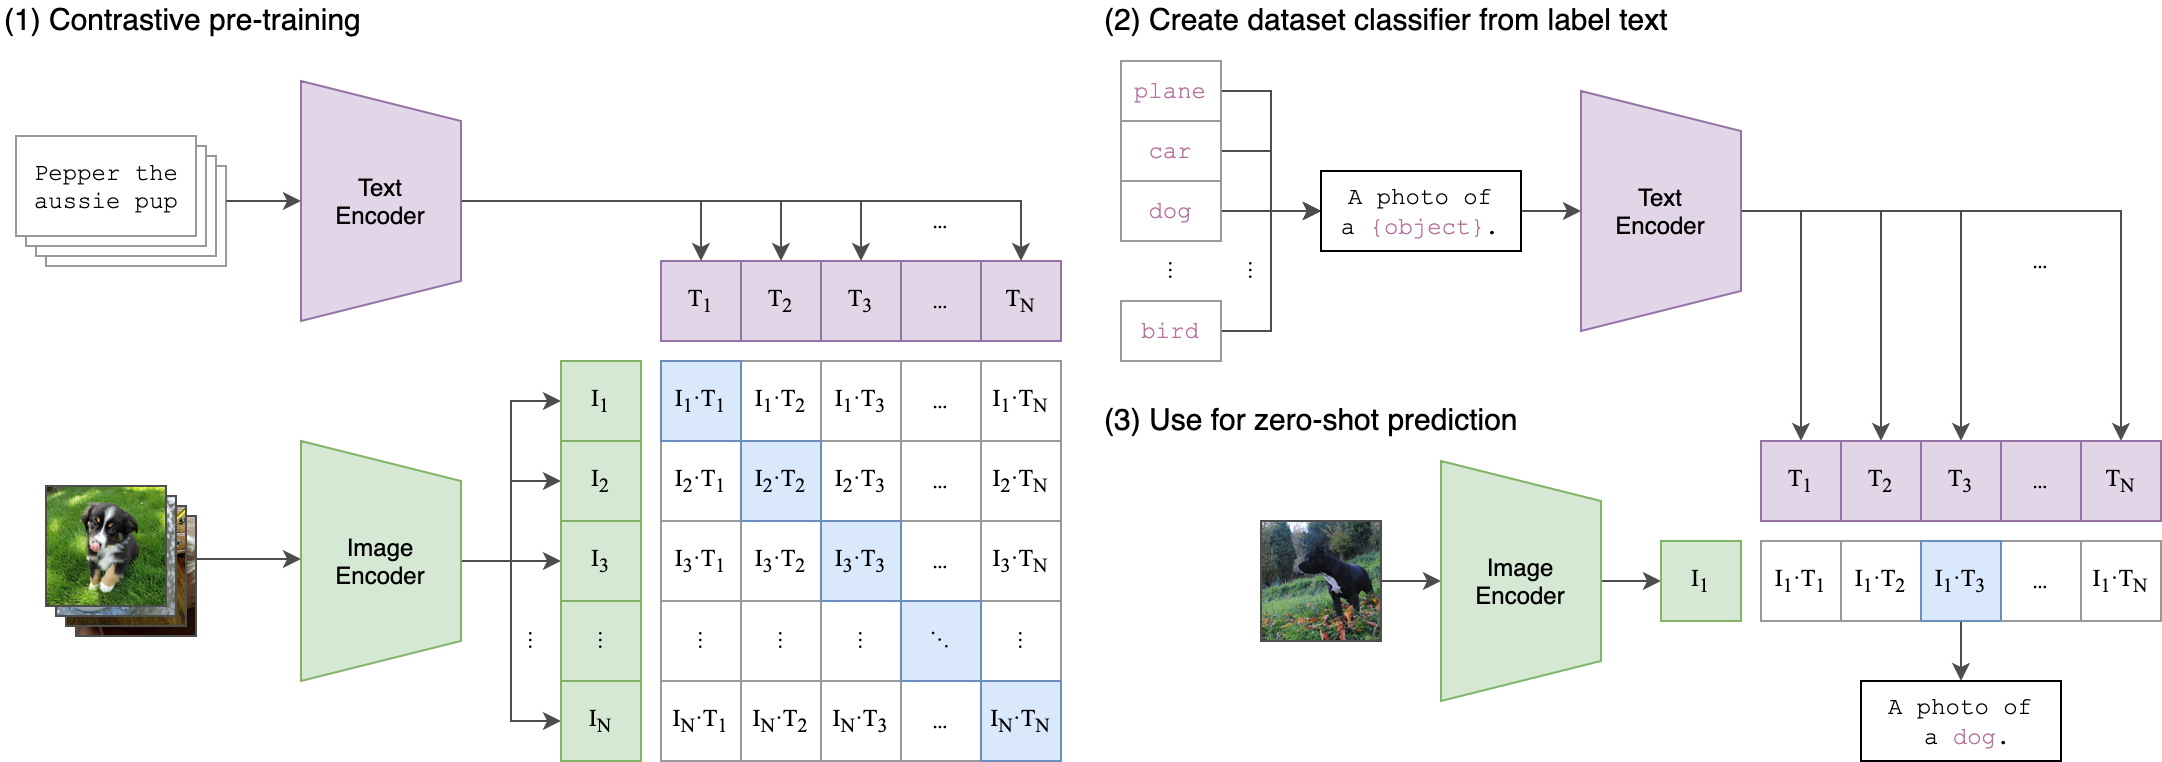
CLIP (Contrastive Language-Image Pre-Training) is a neural network trained on a variety of (image, text) pairs. It can be instructed in natural language to predict the most relevant text snippet, given an image, without directly optimizing for the task, similarly to the zero-shot capabilities of GPT-2 and 3. We found CLIP matches the performance of the original ResNet50 on ImageNet “zero-shot” without using any of the original 1.28M labeled examples, overcoming several major challenges in computer vision.
Approach
Usage
First, install PyTorch 1.7.1 (or later) and torchvision, as well as small additional dependencies, and then install this repo as a Python package. On a CUDA GPU machine, the following will do the trick:
Replace cudatoolkit=11.0 above with the appropriate CUDA version on your machine or cpuonly when installing on a machine without a GPU.
import torch
import clip
from PIL import Image

device = "cuda" if torch.cuda.is_available() else "cpu"
model, preprocess = clip.load("ViT-B/32", device=device)

image = preprocess(Image.open("CLIP.png")).unsqueeze(0).to(device)
text = clip.tokenize(["a diagram", "a dog", "a cat"]).to(device)

with torch.no_grad():
    image_features = model.encode_image(image)
    text_features = model.encode_text(text)

    logits_per_image, logits_per_text = model(image, text)
    probs = logits_per_image.softmax(dim=-1).cpu().numpy()

print("Label probs:", probs)  # prints: [[0.9927937  0.00421068 0.00299572]]
API
The CLIP module clip provides the following methods:
clip.available_models()
Returns the names of the available CLIP models.
clip.load(name, device=..., jit=False)
Returns the model and the TorchVision transform needed by the model, specified by the model name returned by clip.available_models(). It will download the model as necessary. The name argument can also be a path to a local checkpoint.
The device to run the model can be optionally specified, and the default is to use the first CUDA device if there is any, otherwise the CPU. When jit is False, a non-JIT version of the model will be loaded.
Returns a LongTensor containing tokenized sequences of given text input(s). This can be used as the input to the model
The model returned by clip.load() supports the following methods:
model.encode_image(image: Tensor)
Given a batch of images, returns the image features encoded by the vision portion of the CLIP model.
model.encode_text(text: Tensor)
Given a batch of text tokens, returns the text features encoded by the language portion of the CLIP model.
model(image: Tensor, text: Tensor)
Given a batch of images and a batch of text tokens, returns two Tensors, containing the logit scores corresponding to each image and text input. The values are cosine similarities between the corresponding image and text features, times 100.
More Examples
Zero-Shot Prediction
The code below performs zero-shot prediction using CLIP, as shown in Appendix B in the paper. This example takes an image from the CIFAR-100 dataset, and predicts the most likely labels among the 100 textual labels from the dataset.
import os
import clip
import torch
from torchvision.datasets import CIFAR100

# Load the model
device = "cuda" if torch.cuda.is_available() else "cpu"
model, preprocess = clip.load('ViT-B/32', device)

# Download the dataset
cifar100 = CIFAR100(root=os.path.expanduser("~/.cache"), download=True, train=False)

# Prepare the inputs
image, class_id = cifar100[3637]
image_input = preprocess(image).unsqueeze(0).to(device)
text_inputs = torch.cat([clip.tokenize(f"a photo of a {c}") for c in cifar100.classes]).to(device)

# Calculate features
with torch.no_grad():
    image_features = model.encode_image(image_input)
    text_features = model.encode_text(text_inputs)

# Pick the top 5 most similar labels for the image
image_features /= image_features.norm(dim=-1, keepdim=True)
text_features /= text_features.norm(dim=-1, keepdim=True)
similarity = (100.0 * image_features @ text_features.T).softmax(dim=-1)
values, indices = similarity[0].topk(5)

# Print the result
print("\nTop predictions:\n")
for value, index in zip(values, indices):
    print(f"{cifar100.classes[index]:>16s}: {100 * value.item():.2f}%")
The output will look like the following (the exact numbers may be slightly different depending on the compute device):
No homepage URL was recorded for openai/CLIP in TopGit's last sync. The README tab above frequently contains screenshots and demo links, or check the repository description on GitHub.
How active is development on openai/CLIP?
The most recent commit recorded on openai/CLIP was 6 months ago, based on the GitHub push timestamp. The repository has 4.0k forks — one of the better signals of community interest.
How many stars does openai/CLIP have?
openai/CLIP has 34.3k GitHub stars — refresh the page for the live number, or check github.com/openai/CLIP. TopGit mirrors GitHub's count but does not claim minute-by-minute accuracy.
What language is openai/CLIP written in?
openai/CLIP is written primarily in Jupyter Notebook. GitHub's language field is based on the largest share of bytes in the default branch.
What license does openai/CLIP use?
openai/CLIP is released under the MIT license. Always verify the LICENSE file directly on GitHub for the authoritative terms — license strings can be edited out of sync with a project's actual stance.
What topics is openai/CLIP associated with?
GitHub's repository topics for openai/CLIP: "deep-learning", "machine-learning". TopGit's editorial category is AI Tools.
Where do I read more about openai/CLIP?
This TopGit page is a snapshot — the READ ME tab shows the project's own README content (links stripped, images preserved). The GitHub repository at github.com/openai/CLIP is the definitive source.
Read full README in the tab above.
Still deciding about CLIP?
One click hands the question to an AI along with this page — see what it says about CLIP.
 /CLIP