Một mục tích hợp AI trong kho dữ liệu GitHub của TopGit: adbar/trafilatura, 7.1k sao, nhóm AI Tools, Python. Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
Tóm tắt dựng từ metadata GitHub của chính dự án — chưa có bài review TopGit. Trang sẽ tự động cập nhật khi bài review đầy đủ được xuất bản.
VÌ SAO CHƯA CÓ REVIEW
TopGit viết bài đầy đủ cho repo có nhiều sao nhất và được yêu cầu nhiều nhất. Trang này là snapshot trong thời gian chờ — xem README gốc ở tab READ ME.
Trafilatura: Discover Web Content, Extract Text and Metadata
>>> from trafilatura import fetch_url, extract
>>> downloaded = fetch_url("https://github.blog/2019-03-29-leader-spotlight-erin-spiceland/")
>>> extract(downloaded)
'Erin Spiceland is a software engineer and ...'
>>> extract(downloaded, output_format="json", with_metadata=True)
'{"title": "Leader spotlight: Erin Spiceland", "author": "Jessica Rudder", "text": "Erin Spiceland is a software engineer and ..."}'
Introduction
Trafilatura is a comprehensive Python package and command-line tool
designed to gather text from the Web and turn raw HTML into structured,
meaningful data. It includes all necessary
discovery and text processing components to perform web crawling,
downloads, scraping, and extraction of main texts, metadata and
comments. It aims at staying handy and modular: no database is
required, the output can be converted to commonly used formats.
Going from raw HTML to essential parts, it focuses on the actual
content, avoids noise caused by recurring elements (headers,
footers, boilerplate), and makes sense of the data and metadata.
The extractor strikes a balance between limiting noise (precision) and
including all valid parts (recall). It is robust and reasonably fast.
Trafilatura is widely used
across thousands of projects,
including by HuggingFace, IBM, Microsoft Research, NVIDIA, the Allen Institute for AI, Stanford, and the Internet Archive.
Features
Advanced web crawling and text discovery:
Support for sitemaps (TXT, XML) and feeds (ATOM, JSON, RSS)
Smart crawling and URL management (filtering and deduplication)
Parallel processing of online and offline input:
Live URLs, efficient and polite processing of download queues
Previously downloaded HTML files and parsed HTML trees
Robust and configurable extraction of key elements:
Main text (own rule-based extractor with jusText and readability-lxml as fallbacks)
Metadata (title, author, date, site name, categories and tags)
Formatting and structure: paragraphs, titles, lists, quotes, code, line breaks, in-line text formatting
Optional add-ons: language detection, speed optimizations
Multiple output formats:
TXT and Markdown
CSV
JSON
HTML, XML and XML-TEI
Evaluation
Trafilatura consistently outperforms other open-source libraries in text
extraction benchmarks. For more information see the
benchmark section
and the evaluation readme
to run the evaluation with the latest data and packages.
Other evaluations
Most efficient open-source library in ScrapingHub's article extraction benchmark
Best overall tool according to Bien choisir son outil d'extraction de contenu à partir du Web
(Lejeune & Barbaresi 2020)
Best single tool by ROUGE-LSum Mean F1 Page Scores in An Empirical Comparison of Web Content Extraction Algorithms
(Bevendorff et al. 2023)
Documentation
Getting started with Trafilatura
is straightforward. For more information and detailed guides, visit
Trafilatura's documentation:
Installation
Usage:
On the command-line,
With Python,
With R
Core Python functions
Interactive Python Notebook: Trafilatura Overview (in the repository)
Tutorials and use cases
See the video tutorials playlist (multiple languages).
License
This package is distributed under the Apache 2.0 license.
Versions prior to v1.8.0 are under GPLv3+ license.
Contributing
Contributions of all kinds are welcome. Visit the Contributing
page
for more information. Bug reports can be filed on the dedicated issue
page.
Many thanks to the
contributors
who extended the docs or submitted bug reports, features and bugfixes!
Support
If you value this software or depend on it for your product, consider
sponsoring it and contributing to its codebase. Your support
on GitHub or ko-fi.com
will help maintain and enhance this package.
Context
This work started as a PhD project at the crossroads of linguistics and
NLP. This expertise has been instrumental in shaping Trafilatura over
the years. Initially launched to create text databases for research purposes
at the Berlin-Brandenburg Academy of Sciences (DWDS and ZDL units),
this package continues to be maintained and its future depends on community support.
Trafilatura is an Italian word for wire
drawing symbolizing the
refinement and conversion process. It is also the way shapes of pasta
are formed.
Author
Reach out via the software repository or the contact
page for inquiries, collaborations, or
feedback. See also social networks for the latest updates.
Barbaresi, A. Trafilatura: A Web Scraping Library and Command-Line
Tool for Text Discovery and
Extraction, Proceedings
of ACL/IJCNLP 2021: System Demonstrations, 2021, p. 122-131.
Barbaresi, A. "Generic Web Content Extraction with Open-Source
Software",
Proceedings of KONVENS 2019, Kaleidoscope Abstracts, 2019.
Barbaresi, A. "Efficient construction of metadata-enhanced web
corpora",
Proceedings of the 10th Web as Corpus Workshop
(WAC-X), 2016.
Citing Trafilatura
Trafilatura is widely used in the academic domain, chiefly for data
acquisition. Here is how to cite it:
@inproceedings{barbaresi-2021-trafilatura,
  title = {{Trafilatura: A Web Scraping Library and Command-Line Tool for Text Discovery and Extraction}},
  author = "Barbaresi, Adrien",
  booktitle = "Proceedings of the Joint Conference of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing: System Demonstrations",
  pages = "122--131",
  publisher = "Association for Computational Linguistics",
  url = "https://aclanthology.org/2021.acl-demo.15",
  year = 2021,
}
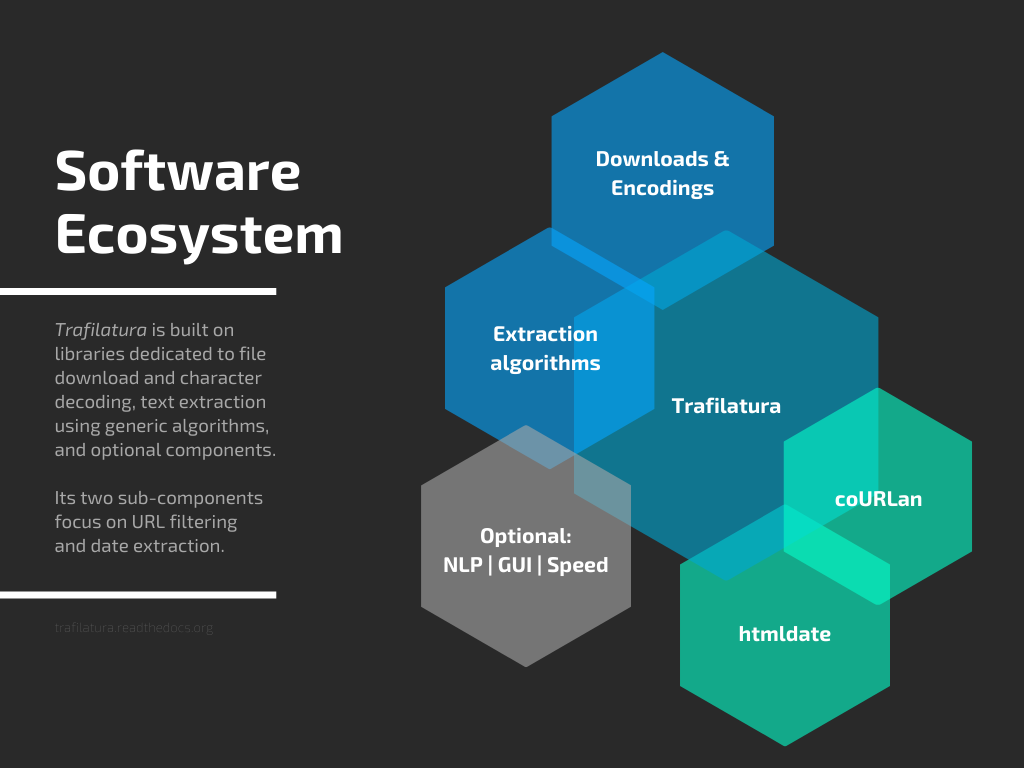
Software ecosystem
Jointly developed plugins and additional packages also contribute to the
field of web data extraction and analysis:
Corresponding posts can be found on Bits of
Language.
Có — adbar/trafilatura phát hành theo license Apache-2.0, nghĩa là mã nguồn mở để đọc, fork và (tùy license) tái sử dụng. Mã: github.com/adbar/trafilatura.
adbar/trafilatura có trang demo không?
Dự án có trang chủ ở https://trafilatura.readthedocs.io. Tab "Readme" ở trang này thường có ảnh chụp và hướng dẫn bắt đầu nhanh.
adbar/trafilatura dùng license gì?
adbar/trafilatura phát hành theo license Apache-2.0. Nên mở file LICENSE trên GitHub để xác nhận — license metadata đôi khi lệch với thực tế dự án.
adbar/trafilatura là gì?
adbar/trafilatura (adbar/trafilatura) là dự án Python trên GitHub. Theo mô tả gốc: Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
Cùng nhóm AI Tools còn repo nào?
adbar/trafilatura thuộc nhóm AI Tools trên TopGit, cùng 20 topic GitHub. Trang Trending và Topics liệt kê các repo cùng số sao và cùng ngôn ngữ để so sánh.
Đọc thêm về adbar/trafilatura ở đâu?
Trang TopGit này là một snapshot — tab "Readme" hiển thị nguyên văn README của repo (đã bỏ link, giữ ảnh). Repo GitHub ở github.com/adbar/trafilatura là nguồn chính thức.
Vì sao adbar/trafilatura được xếp vào nhóm AI Tools?
TopGit xếp adbar/trafilatura vào nhóm AI Tools dựa trên GitHub topics và mô tả của repo (gắn thẻ: "article-extractor", "corpus-builder", "corpus-tools"). Việc phân loại dựa trên metadata thật của repo, không phải đoán theo cảm tính biên tập.
Đọc đầy đủ README ở tab phía trên.
Muốn nghe thêm một ý kiến về trafilatura?
Hỏi một AI đọc được trang này — một cú bấm là có ngay nhận định về trafilatura.

 /trafilatura