Trên GitHub, NMAC427/SwiftOCR đã đạt 4.6k sao, nhóm Mobile, ngôn ngữ Swift. Fast and simple OCR library written in Swift
Tóm tắt dựng từ metadata GitHub của chính dự án — chưa có bài review TopGit. Trang sẽ tự động cập nhật khi bài review đầy đủ được xuất bản.
VÌ SAO CHƯA CÓ REVIEW
TopGit viết bài đầy đủ cho repo có nhiều sao nhất và được yêu cầu nhiều nhất. Trang này là snapshot trong thời gian chờ — xem README gốc ở tab READ ME.
⛔️ This Project is deprecated and no longer gets maintained!
Please use Apple's Vision framework instead of SwiftOCR. It is very fast, accurate and much less finicky.
SwiftOCR
SwiftOCR is a fast and simple OCR library written in Swift. It uses a neural network for image recognition.
As of now, SwiftOCR is optimized for recognizing short, one line long alphanumeric codes (e.g. DI4C9CM). We currently support iOS and OS X.
Features
Easy to use training class
High accuracy
Great default image preprocessing
Fast and accurate character segmentation algorithm
Add support for lowercase characters
Add support for connected character segmentation
Why should I choose SwiftOCR instead of Tesseract?
This is a really good question.
If you want to recognize normal text like a poem or a news article, go with Tesseract, but if you want to recognize short, alphanumeric codes (e.g. gift cards), I would advise you to choose SwiftOCR because that's where it exceeds.
Tesseract is written in C++ and over 30 years old. To use it you first have to write a Objective-C++ wrapper for it. The main issue that's slowing down Tesseract is the way memory is managed. Too many memory allocations and releases slow it down.
I did some testing on over 50 difficult images containing alphanumeric codes. The results where astonishing. SwiftOCR beat Tesseract in every category.
SwiftOCR
Tesseract
Speed
0.08 sec.
0.63 sec.
Accuracy
97.7%
45.2%
CPU
~30%
~90%
Memory
45 MB
73 MB
How does it work?
Input image is thresholded (binarized).
Characters are extracted from the image, using a technique called Connected-component labeling.
Separated characters are converted into numbers, which are then fed into the neural network.
How to use it?
SwiftOCR is available through CocoaPods. To install it, simply add the following line to your Podfile:
pod 'SwiftOCR'
If you ever used Tesseract you know how exhausting it can be to implement OCR into your project.
SwiftOCR is the exact opposite of Tesseract. It can be implemented using just 6 lines of code.
import SwiftOCR

let swiftOCRInstance = SwiftOCR()

swiftOCRInstance.recognize(myImage) { recognizedString in
    print(recognizedString)
}
To improve your experience with SwiftOCR you should set your Build Configuration to Release.
Training
Training SwiftOCR is pretty easy. There are only a few steps you have to do, before it can recognize a new font.
The easiest way to train SwiftOCR is using the training app that can be found under /example/OS X/SwiftOCR Training. First select the fonts you want to train from the list. After that, you can change the characters you want to train in the text field. Finally, you have to press the Start Testing button. The only thing that's left now, is waiting. Depending on your settings, this can take between a half and two minutes. After about two minutes you may manually stop the training.
Pressing the Save button will save trained network to your desktop.
The Test button is used for evaluating the accuracy of the trained neural network.
Examples
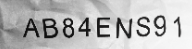
Here is an example image. SwiftOCR has no problem recognizing it. If you try to recognize the same image using Tesseract the output is 'LABMENSW' ?!?!?.
This image is difficult to recognize because of two reasons:
The lighting is uneven. This problem is solved by the innovative preprocessing algorithm of SwiftOCR.
The text in this image is distorted. Since SwiftOCR uses a neural network for the recognition, this isn't a real problem. A NN is flexible like a human brain and can recognize even the most distorted image (most of the time).
TODO
Port to GPUImage 2
Dependencies
Swift-AI
GPUImage
Union-Find
License
The code in this repository is licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at

   http://www.apache.org/licenses/LICENSE-2.0

Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
NOTE: This software depends on other packages that may be licensed under different open source licenses.
NMAC427/SwiftOCR thuộc nhóm Mobile trên TopGit, cùng 9 topic GitHub. Trang Trending và Topics liệt kê các repo cùng số sao và cùng ngôn ngữ để so sánh.
Đọc thêm về NMAC427/SwiftOCR ở đâu?
Trang TopGit này là một snapshot — tab "Readme" hiển thị nguyên văn README của repo (đã bỏ link, giữ ảnh). Repo GitHub ở github.com/NMAC427/SwiftOCR là nguồn chính thức.
NMAC427/SwiftOCR có phải mã nguồn mở không?
Có — NMAC427/SwiftOCR phát hành theo license Apache-2.0, nghĩa là mã nguồn mở để đọc, fork và (tùy license) tái sử dụng. Mã: github.com/NMAC427/SwiftOCR.
NMAC427/SwiftOCR là gì?
NMAC427/SwiftOCR (NMAC427/SwiftOCR) là dự án Swift trên GitHub. Theo mô tả gốc: Fast and simple OCR library written in Swift
NMAC427/SwiftOCR so với các dự án Mobile khác thế nào?
NMAC427/SwiftOCR được TopGit xếp vào nhóm Mobile, với 4.6k sao GitHub và viết bằng Swift. Xem trang chủ đề Mobile trên TopGit để so sánh với các dự án tương tự theo số sao và mức độ hoạt động.
Vì sao NMAC427/SwiftOCR được xếp vào nhóm Mobile?
TopGit xếp NMAC427/SwiftOCR vào nhóm Mobile dựa trên GitHub topics và mô tả của repo (gắn thẻ: "deprecated", "ios", "macos"). Việc phân loại dựa trên metadata thật của repo, không phải đoán theo cảm tính biên tập.
Đọc đầy đủ README ở tab phía trên.
SwiftOCR có đáng để bạn bỏ thời gian?
ChatGPT, Claude và Perplexity đều đọc được trang này. Hỏi thử xem họ nghĩ gì về SwiftOCR.

 /SwiftOCR