Snapshot summary built from the project's own GitHub metadata — there's no written TopGit review yet. The page will update automatically when a full review is published.
WHY NO REVIEW YET
TopGit writes full reviews for the most-starred, most-requested repositories. This page is a snapshot until then — see the READ ME tab for the original README in full.
InternLM is a multilingual large language model jointly developed by Shanghai AI Lab and SenseTime (with equal contribution), in collaboration with the Chinese University of Hong Kong, Fudan University, and Shanghai Jiaotong University.
Technical report: [PDF]
Note: Please right click the link above to directly download the PDF file.
Abstract
We present InternLM, a multilingual foundational language model with 104B parameters. InternLM is pre-trained on a large corpora with 1.6T tokens with a multi-phase progressive process, and then fine-tuned to align with human preferences. We also developed a training system called Uniscale-LLM for efficient large language model training. The evaluation on a number of benchmarks shows that InternLM achieves state-of-the-art performance in multiple aspects, including knowledge understanding, reading comprehension, mathematics, and coding. With such well-rounded capabilities, InternLM achieves outstanding performances on comprehensive exams, including MMLU, AGIEval, C-Eval and GAOKAO-Bench, without resorting to external tools. On these benchmarks, InternLM not only significantly outperforms open-source models, but also obtains superior performance compared to ChatGPT. Also, InternLM demonstrates excellent capability of understanding Chinese language and Chinese culture, which makes it a suitable foundation model to support Chinese-oriented language applications. This manuscript gives a detailed study of our results, with benchmarks and examples across a diverse set of knowledge domains and tasks.
Main Results
As latest large language models begin to exhibit human-level intelligence,
exams designed for humans, such as China's college entrance examination and US SAT and GRE,
are considered as important means to evaluate language models.
Note that in its technical report on GPT-4, OpenAI tested GPT-4
through exams across multiple areas and used the exam scores as the key results.
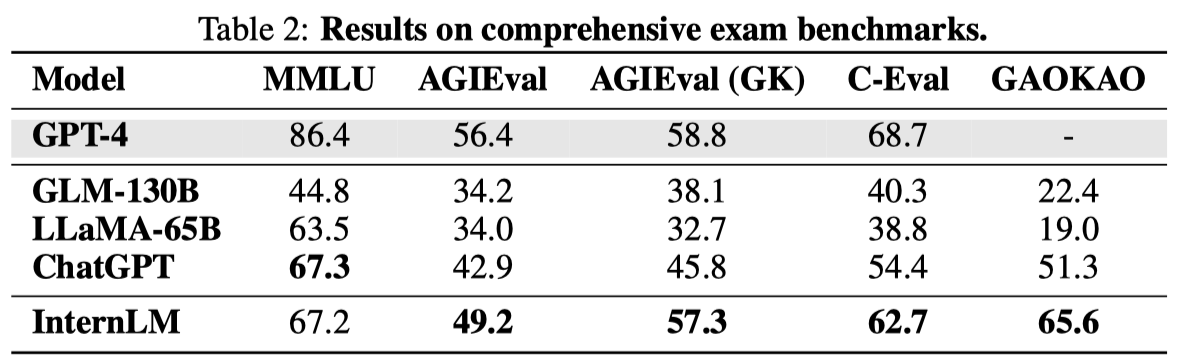
We tested InternLM in comparison with others on four comprehensive exam benchmarks,
as below:
MMLU:
A multi-task benchmark constructed based on various US exams,
which covers elementary mathematics, physics, chemistry, computer science, American history, law, economics, diplomacy, etc.
AGIEval:
A benchmark developed by Microsoft Research to evaluate the ability of language models through human-oriented exams, which comprises 19 task sets derived from various exams in China and the United States, e.g., the college entrance exams and lawyer qualification exams in China, and SAT, LSAT, GRE and GMAT in the United States.
Among the 19 task sets, 9 sets are based on the Chinese college entrance exam (Gaokao), which we single out as an important collection named AGIEval (GK).
C-Eval:
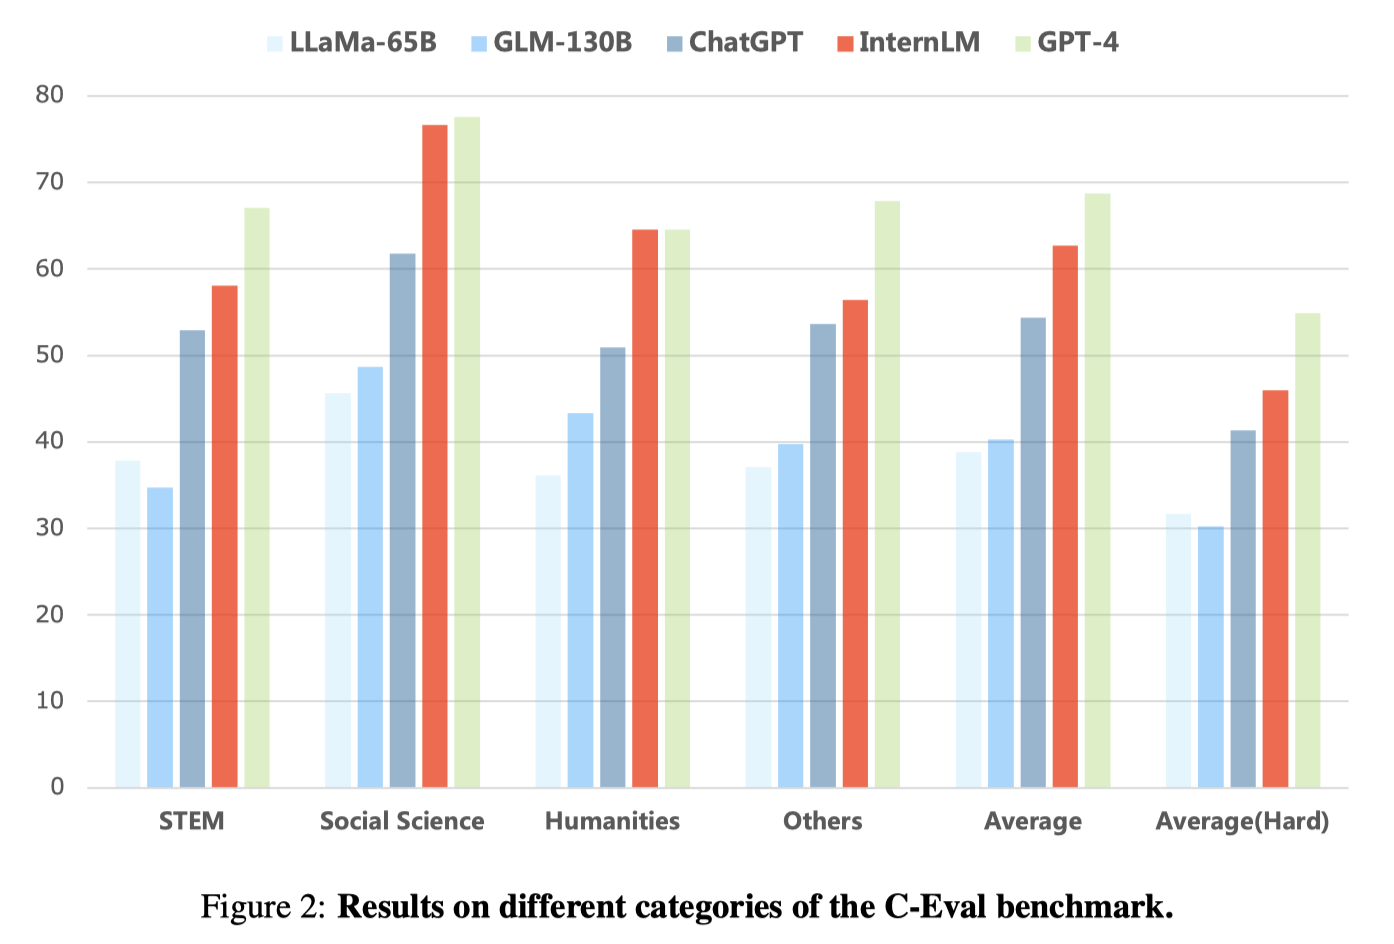
A comprehensive benchmark devised to evaluate Chinese language models, which
contains nearly 14,000 questions in 52 subjects, covering mathematics, physics,
chemistry, biology, history, politics, computer and other disciplines, as well as
professional exams for civil servants, certified accountants, lawyers, and doctors.
GAOKAO-Bench:
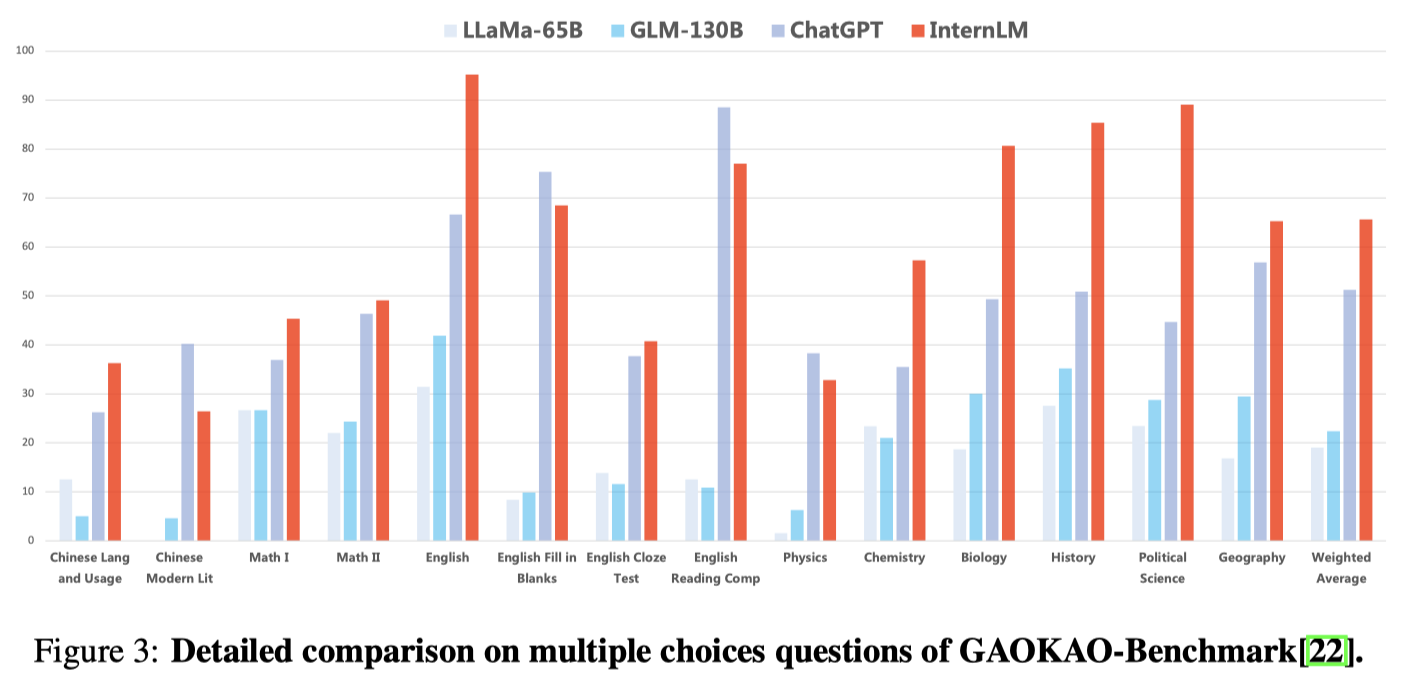
A comprehensice benchmark based on the Chinese college entrance exams, which
include all subjects of the college entrance exam. It provide different types
of questions, including multiple-choices, blank filling, and QA.
For conciseness, we call this benchmark simply as Gaokao.
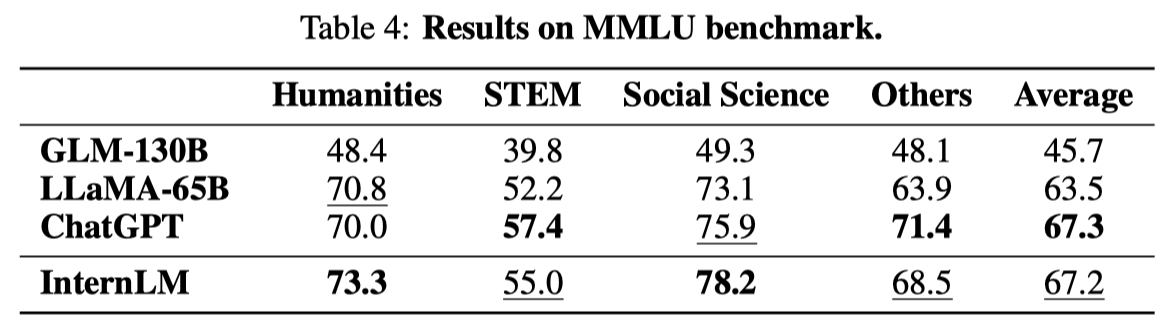
Results on MMLU
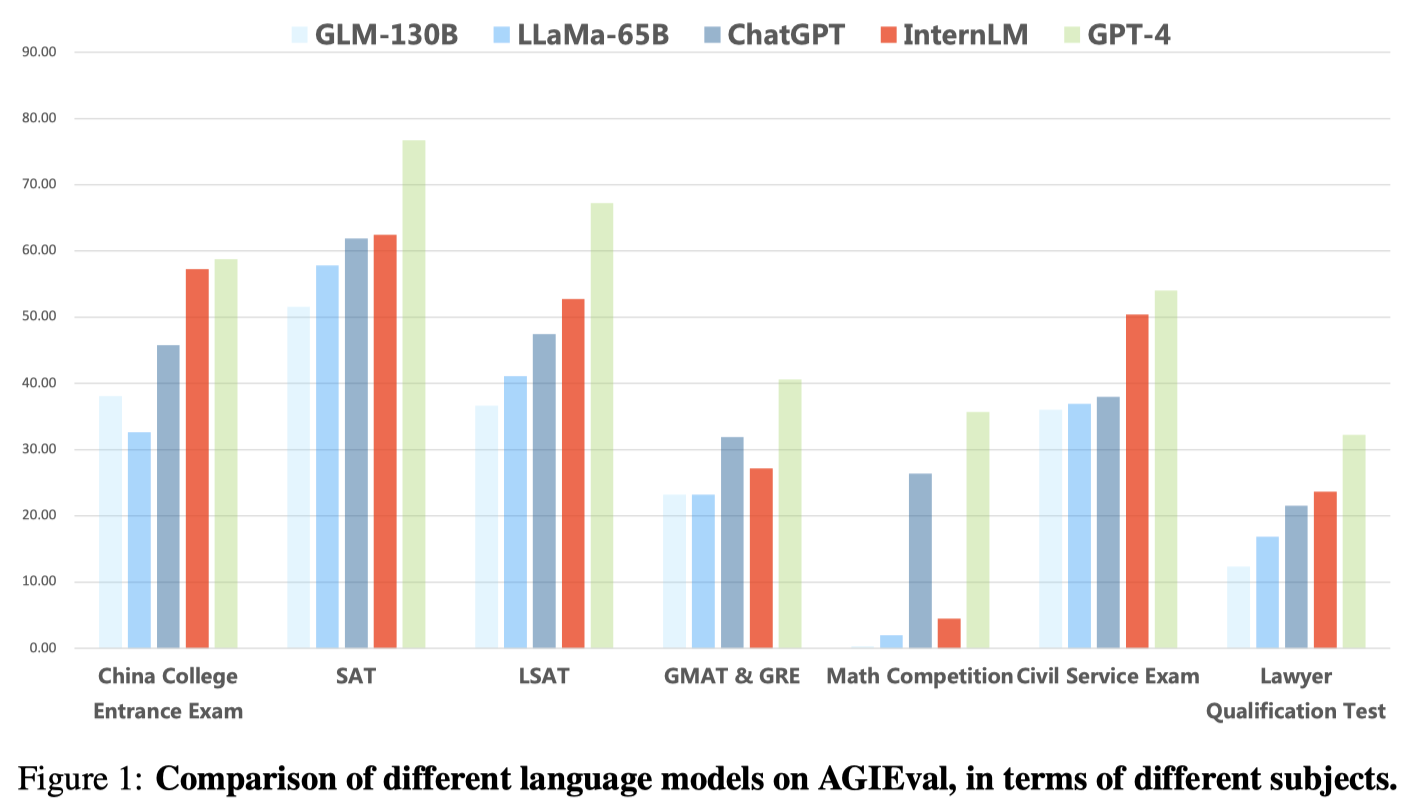
Results on AGIEval
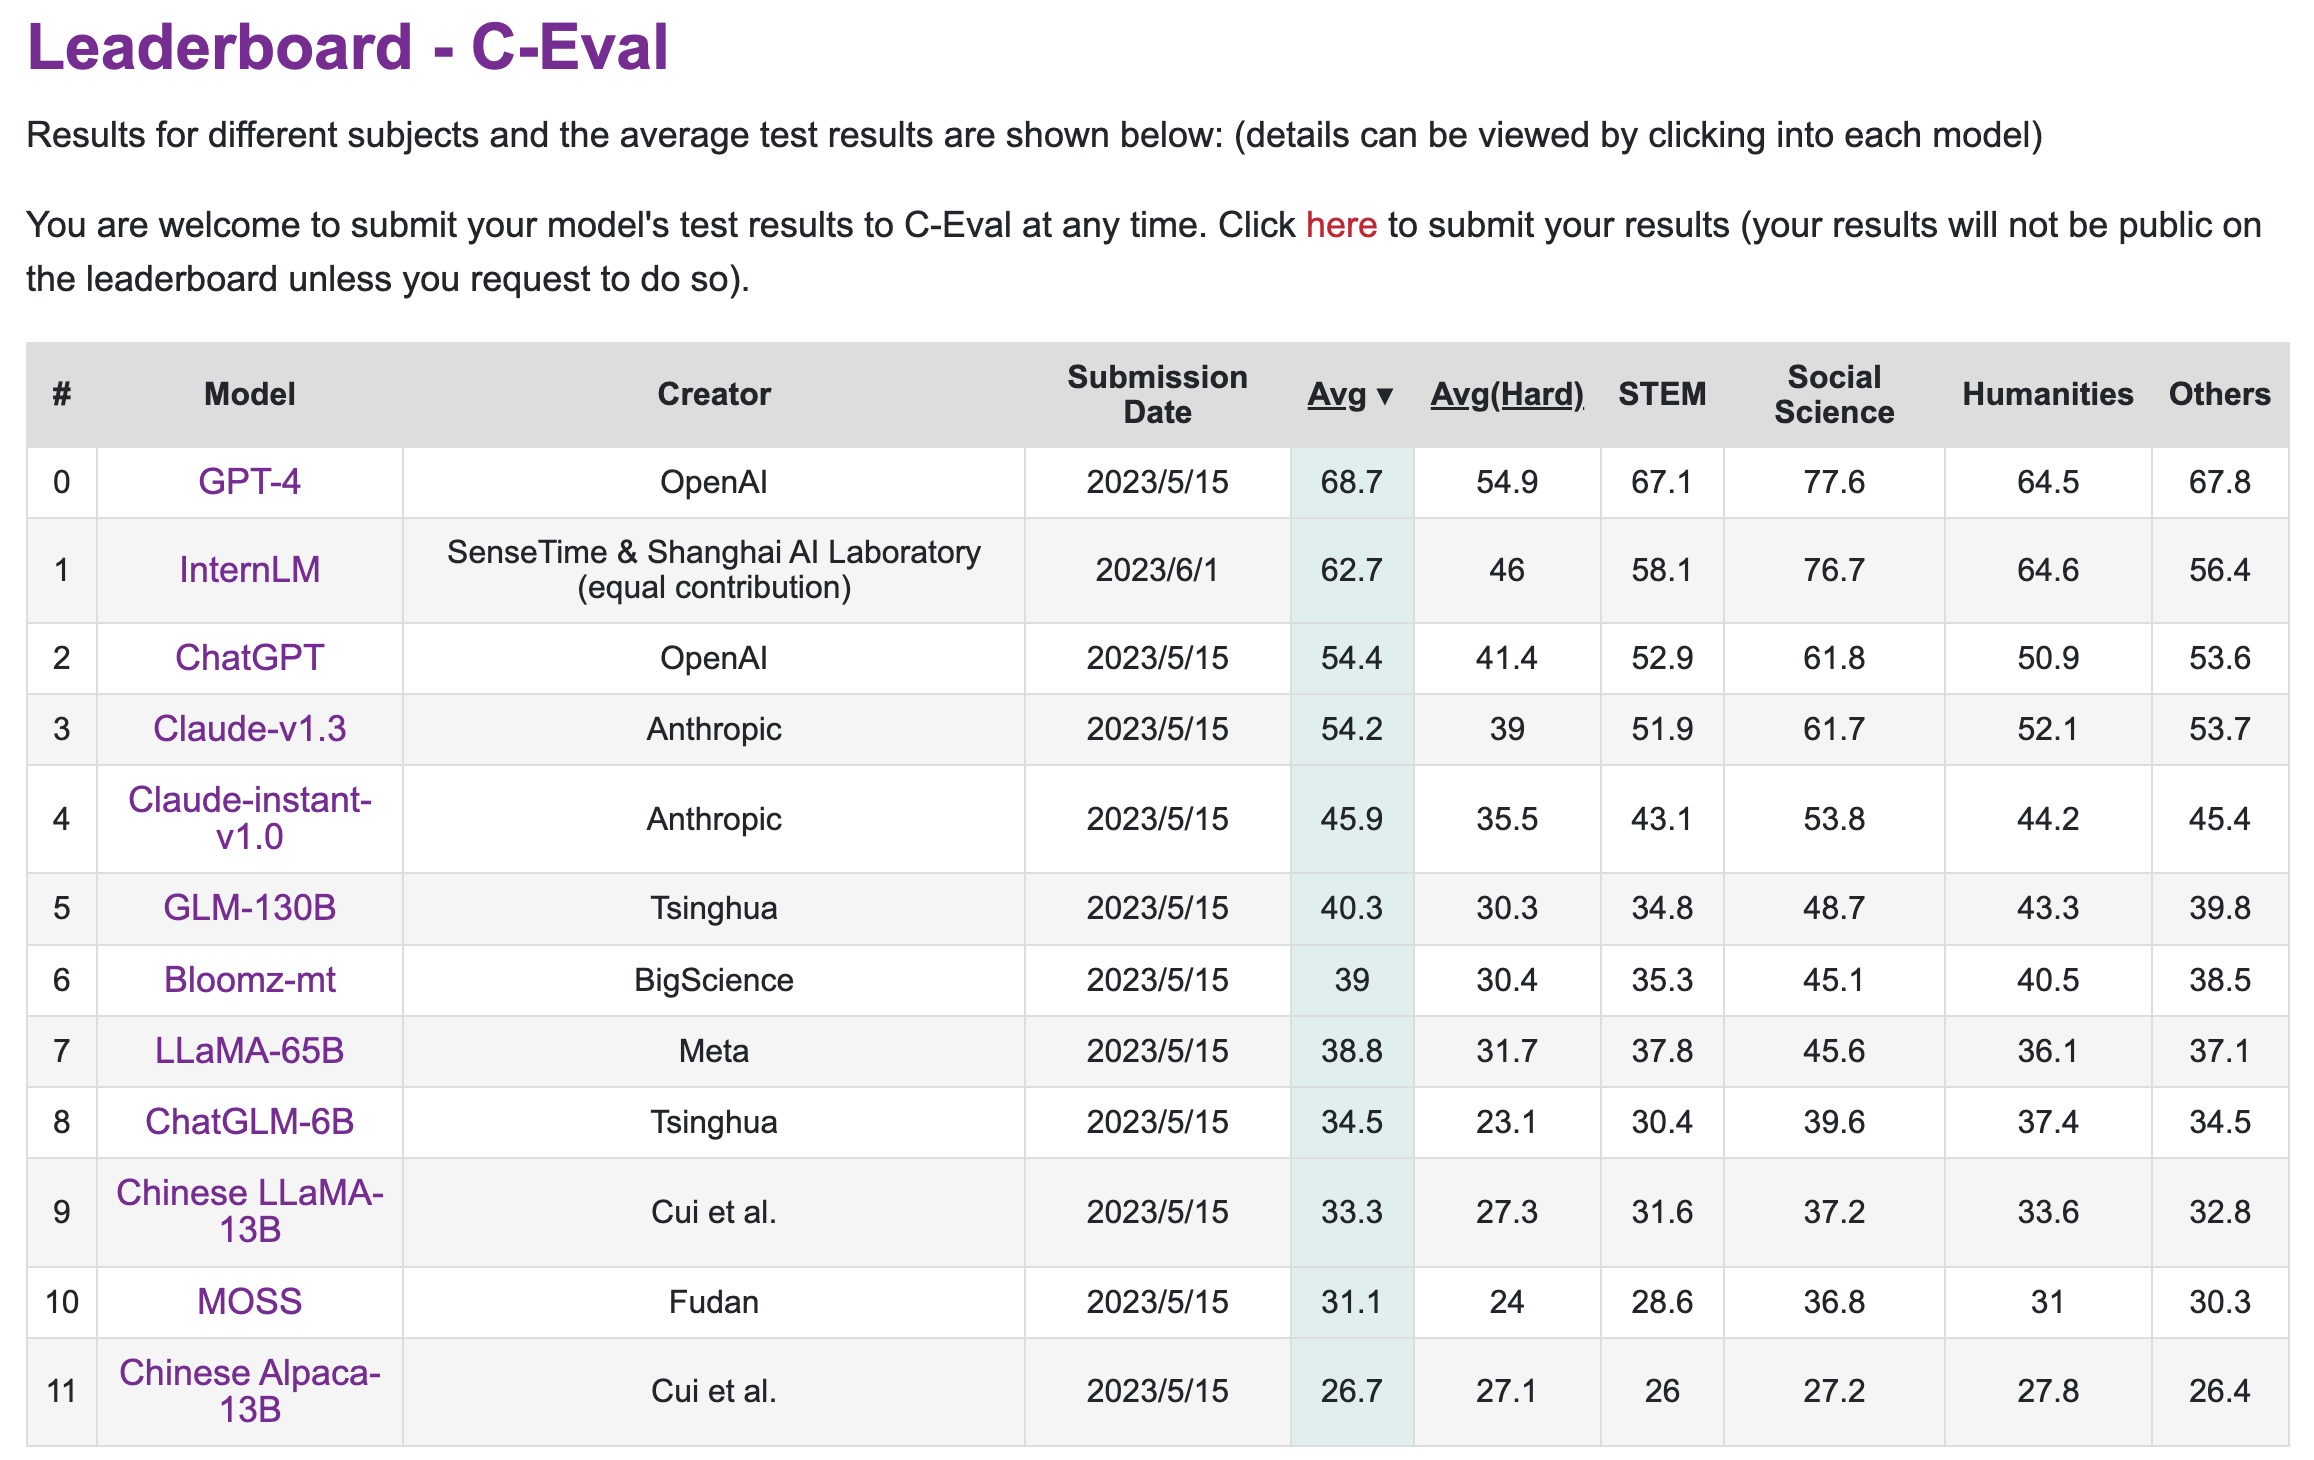
Results on C-Eval
C-Eval has a live leaderboard. Below is a screenshot that shows all
the results (as of 2023-06-01).
Results on GAOKAO-Benchmark
Benchmarks in Specific Aspects
We also tested InternLM in comparison with others in multiple aspects:
Knowledge QA: TriviaQA and NaturalQuestions.
Reading Comprehension: RACE
Chinese Understanding: CLUE and FewCLUE
Mathematics: GSM8k and MATH
Coding: HumanEval and MBP
Please refer to our technical report for detailed results.
We are working on more tests, and will share new results as our work proceeds.
Citation
You can cite this technical report like this:
@misc{2023internlm,
    title={InternLM: A Multilingual Language Model with Progressively Enhanced Capabilities},
    author={InternLM Team},
    howpublished = {\url{https://github.com/InternLM/InternLM-techreport}},
    year={2023}
}
TopGit's last sync did not record any GitHub topics for InternLM/InternLM-techreport. GitHub topics appear in the right sidebar of a repository page; that's the authoritative place to check.
How active is development on InternLM/InternLM-techreport?
The most recent commit recorded on InternLM/InternLM-techreport was 3.5 years ago, based on the GitHub push timestamp. The repository has 25 forks — one of the better signals of community interest.
How many stars does InternLM/InternLM-techreport have?
InternLM/InternLM-techreport has 891 GitHub stars — refresh the page for the live number, or check github.com/InternLM/InternLM-techreport. TopGit mirrors GitHub's count but does not claim minute-by-minute accuracy.
What is InternLM/InternLM-techreport?
InternLM/InternLM-techreport (InternLM/InternLM-techreport) is a multi-language project tracked by TopGit. The repository has 891 GitHub stars at the time of our last sync.
What language is InternLM/InternLM-techreport written in?
TopGit's last sync did not record a primary language for InternLM/InternLM-techreport. Open the repository on GitHub to see the full breakdown by file extension.
Read full README in the tab above.
Is InternLM-techreport worth your time?
ChatGPT, Claude and Perplexity can all read this page. Ask one of them what it makes of InternLM-techreport.

 /InternLM-techreport